01
Performance audit
Profiling across servers, databases and frontends that finds exactly where time and money are being lost.
ServiceWeb Challengers
Evidence-led performance and security engineering: we measure what's slow, test what's exposed, and fix the causes that matter — instead of applying generic optimisation checklists.
Slow platforms and security holes are usually treated with folklore: a caching plugin here, a security scanner there. We work differently — profiling tools, server logs and request traces tell us exactly where the milliseconds go and where the exposure is. Then we fix those things and nothing else.
Performance work has a business case and we quantify it: which pages lose users, which queries waste money, what a faster checkout is worth. When the evidence is on the table, priorities become obvious and the fixes pay for themselves.
Security is treated as risk management, not theatre. We identify what's genuinely exposed — out of date runtimes, leaked credentials, unprotected admin, injection paths — and close the gaps by real likelihood and impact, in an order that makes sense.
Diagnosis from profiling and logs, not folklore
Fixes prioritised by business impact
Security addressed by real risk, not checklists
Improvements verified with before-and-after numbers
Start with a focused audit; continue with the fixes ranked by what they're worth to you.
Profiling across servers, databases and frontends that finds exactly where time and money are being lost.
Query fixes, caching layers, asset pipelines and CDNs — each change verified against measurements.
Exposure testing across dependencies, access, configuration and code — findings ranked by real risk.
The fixes implemented properly: patching, access control, headers, WAF rules and input handling.
Compromised or failing platforms cleaned, restored and hardened — with the entry point closed and documented.
Uptime, error and vulnerability monitoring tuned to your platform, so the next issue finds you first.
Real project patterns connected to this service, solution or industry experience.
View all case studies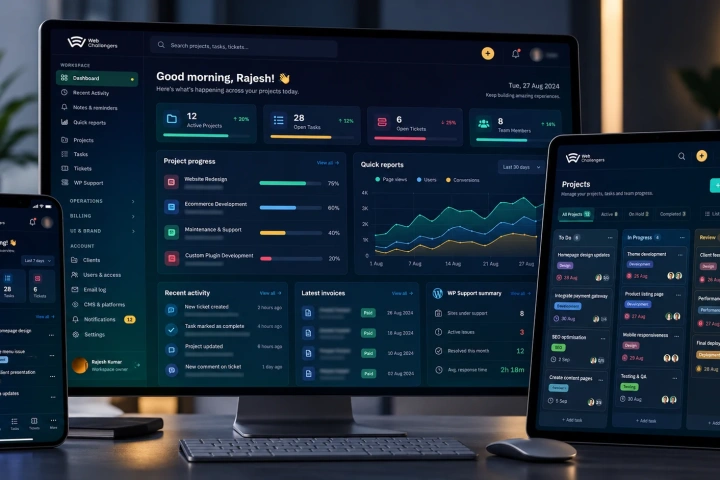
A secure Laravel + Vue platform unifying projects, clients, teams, support, billing and bulk WordPress operations — built to make 400–700+ website estates practical to manage from one place.
View case study↗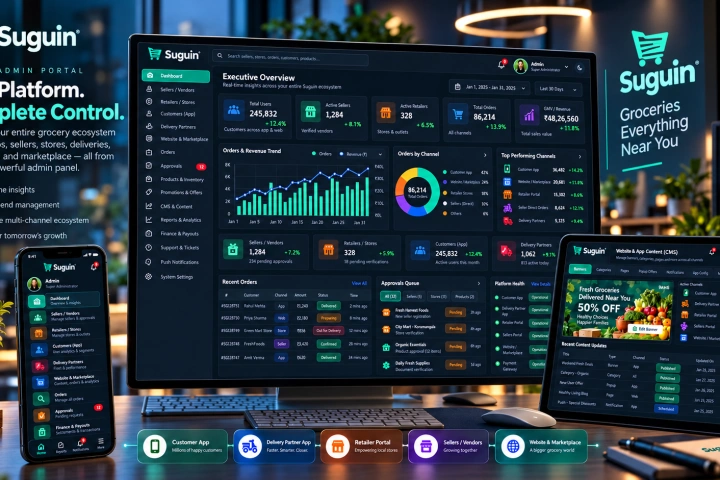
The Laravel and MySQL core of the Suguin ecosystem, managing sellers, retailers, customers, delivery partners, catalogues, orders, content, promotions, approvals, payouts, support and platform-wide controls.
View case study↗A short loop with proof at every step — you see the numbers before and after.
Profiling, scanning and log analysis produce an evidence base: what's slow, what's exposed, what it costs.
Findings ranked by impact and effort — the report shows what to fix first and what it's worth.
Remediation implemented on staging, verified with the same measurements that found the problem.
Monitoring and scheduled re-checks keep the platform fast and safe after we step back.
Scores are proxies; experience is the goal. A 0.2-second improvement on your checkout usually beats a 15-point Lighthouse gain on a page nobody visits. We measure real journeys on real devices and optimise the slow paths that carry the most traffic and revenue.
Security budgets disappear fastest when chasing the threat that made the news instead of the one that fits your platform. Unpatched runtimes, reused passwords and forgotten admin accounts compromise far more sites than exotic attacks — we close the boring doors first, because they're the ones being opened.
Straight answers about how this work is scoped, delivered and supported.
Ask something else →That's precisely our entry point. Profiling and log analysis pinpoint the actual bottleneck — database, code, infrastructure or third parties — and we fix that first.
Contact us immediately. We isolate, preserve evidence, clean and restore the platform, close the entry point and document what happened — usually within days, not weeks.
Rarely. Most work is staged and released with verification; anything riskier is scheduled around your traffic with a rollback prepared.
Yes — we regularly diagnose and tune platforms on third-party hosting, coordinating changes with your provider where access is needed.
Describe the symptom — sluggish pages, a scare, a nagging doubt. We'll investigate, show you the evidence and fix what's actually wrong.
Request a review ↗